Data centers are expected to stay operational all the time.
Not “most of the time.”
Not “when conditions are ideal.”
All the time.
Because when critical infrastructure goes down, the impact spreads fast — across operations, communications, customers, applications, supply chains, and revenue.
That’s why mission-critical data center infrastructure requires more than redundant hardware and optimistic SLAs.
It requires operational readiness.
Always-on environments need reliable networks, proactive monitoring, and fast technical support. These systems help teams identify and resolve problems before they cause outages.
Because in mission-critical operations, uptime is never accidental.
Always-On Means No Margin for Error
Modern data centers do not close, they do not pause, and they do not get a second chance.
Data centers operate 24/7/365 because the businesses they support depend on constant connectivity. From financial systems and healthcare networks to logistics platforms and enterprise applications, uptime protects revenue, customer trust, and service commitments.
Even brief outages can have serious consequences, including lost transactions, service-level agreement (SLA) penalties, damage to a company’s reputation, and disruptions that affect the entire organization.
In this environment, infrastructure reliability is not a performance metric. It is a foundational requirement. Always-on means no margin for error.
What Is Mission-Critical Infrastructure?
Mission-critical infrastructure refers to systems, facilities, and technologies that must remain operational to support essential business functions, communications, security, or service delivery.
In data center environments, mission-critical infrastructure may include:
- Core network systems
- Enterprise wireless infrastructure
- Power and backup systems
- Environmental monitoring
- Security systems
- Connectivity infrastructure
- Cloud and edge networking
- Monitoring platforms
- Cooling systems
- Communication systems
When mission-critical infrastructure fails, businesses can face service outages, financial losses, and compliance risks. Reliable systems, ongoing monitoring, and fast response times help reduce these risks.
What “Always-On Infrastructure” Really Requires
Redundancy is essential, however redundancy alone is not enough.
Always-on infrastructure depends on reliable physical and network systems. Structured cabling must be installed correctly, wireless coverage must be tested, and hardware installations must follow consistent standards.
Reliable performance requires thorough testing and documentation. Teams must test network designs, verify installations, and maintain accurate records that are easy to access.
Because when something fails, and eventually something will, clarity and consistency determine recovery speed. Always-on infrastructure is engineered, not assumed.
What Challenges Do Mission-Critical Data Centers Face?
Today’s data centers are evolving at a relentless pace.
- Rapid expansion and increasing density. Higher compute loads, tighter rack configurations, and growing power demands strain legacy designs.
- Complex cabling and network environments. More devices, more connections, more potential failure points.
- Inconsistent installation practices across locations. Multi-site enterprises often struggle to maintain uniform standards.
- Limited visibility into network performance and coverage. Blind spots remain hidden until performance degrades.
For infrastructure-heavy organizations operating across multiple states, inconsistency compounds risk, and misstep in one facility becomes a pattern across many.
Complexity is not the enemy. Lack of discipline is.
The Real Cost of Downtime for Data Centers
Most organizations calculate downtime in minutes.
The real damage usually lasts much longer.
Mission-critical outages can impact:
- Customer access
- Internal communications
- Operational workflows
- Security systems
- Inventory systems
- Data availability
- Remote connectivity
- Supply chain operations
- Compliance requirements
- Revenue generation
In industries like healthcare, logistics, manufacturing, retail, and telecommunications, even short disruptions can create ripple effects across the entire organization.
The issue is rarely just “the network went down.”
It’s everything that stopped functioning because it did.
Technology as the First Line of Defense
Technology protects uptime when it is implemented with intention.
Designing for reliability begins with predictive site surveys and network modeling. These tools eliminate guesswork, ensuring wireless placement, signal strength, and network architecture are optimized from day one.
Capacity planning helps data centers prepare for growth. Infrastructure must support current workloads and future expansion. But good design is only the beginning. Teams must also test network performance under real-world conditions.
Key steps include:
-
Capacity planning: Prepare infrastructure for current demands and future growth.
-
Active site surveys: Test wireless coverage and identify potential connectivity issues.
-
Heat mapping: Confirm wireless coverage and identify areas with weak signals.
-
Post-installation testing: Verify wired and wireless network performance under load.
Blind spots discovered during peak usage are expensive, but blind spots discovered during validation are manageable. Testing is protection.
The Importance of Expert Field Services
Always-on environments demand specialized technicians. Deployments occur in live facilities where downtime is unacceptable, and security protocols are strict. Access control, compliance requirements, and operational coordination are non-negotiable.
Inconsistent installation practices create unnecessary risks. Poor cable connections, inconsistent labeling, and undocumented changes may seem like small issues. But they can delay repairs when an outage occurs.
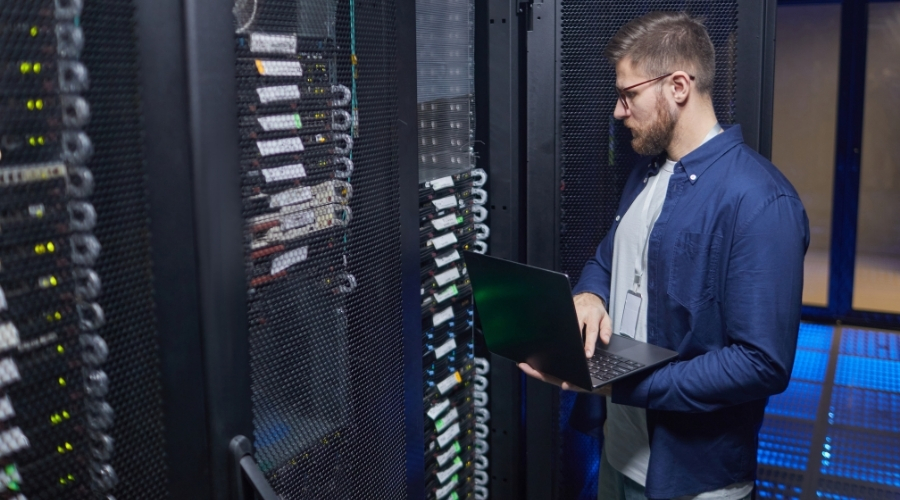
Experienced field service technicians help reduce these risks. They know how to work in active data centers without disrupting operations. They follow consistent procedures, document their work, and complete installations with precision.
For enterprises with national footprints, repeatability is essential. The same quality in every facility, the same disciplined process, and the same accountability. That is scalability with true presence across the United States, Canada, and U.S. Territories.
How FSS Supports Always-On Data Center Infrastructure
FSS delivers nationwide service coverage designed for consistent execution at scale. Whether supporting a single flagship facility or a multi-state portfolio of data centers, our teams deploy with uniform standards.
Our network and infrastructure services are tailored for mission-critical environments:
- Structured cabling, rack and stack
- Wireless and wired network installations
- Device staging, configuration, and deployment
- Active validation and performance testing
Every project includes careful project management and quality checks designed to protect uptime. Our teams follow clear processes, maintain open communication, and document their work.
Speed matters during expansions, upgrades, and urgent repairs. FSS responds quickly without sacrificing quality. Our teams work to minimize disruptions while protecting long-term reliability.
And because we are partnership-driven, our focus extends beyond the immediate install. We align with enterprise objectives, supporting sustained operational excellence rather than short-term fixes.
Beyond Deployment: Maintaining Reliability Over Time
Keeping data centers running requires ongoing testing and monitoring. Detailed reports and accurate records help teams identify problems, troubleshoot faster, and meet compliance requirements.
As workloads grow and technology changes, data centers need upgrades that won’t disrupt operations. FSS supports phased installations, equipment replacements, and network improvements that help keep systems running.
Proactive optimization prevents reactive scrambling. Reliability is sustained through vigilance, not luck.
Building Infrastructure That Can Withstand Change
Data centers are constantly changing. They expand, migrate, and adopt new technologies. Infrastructure must keep up with growing equipment demands and changing business needs. Without the right support, growth can create reliability problems.
FSS supports expansions, migrations, and retrofits with standardized processes that protect consistency across facilities. Our national footprint ensures rapid deployment wherever your operations demand it.
Scalable infrastructure supports growth, while fast deployment helps projects stay on schedule. Strong partnerships help ensure technology decisions support long-term business goals.
For large, collaborative enterprises with U.S. headquarters and multi-state operations, that combination is not optional. It is strategic.
Uptime Is Built, Not Assumed
Always-on performance doesn’t happen by accident. It starts with reliable cabling, tested networks, consistent installations, and accurate documentation. Long-term uptime also depends on scalable infrastructure, fast support, and trusted partnerships.
Mission-critical data centers need service partners who understand that every minute matters. FSS delivers reliable, scalable infrastructure support to help data centers across North America stay operational.
FSS stands as that partner: delivering reliable, scalable infrastructure in mission-critical environments across North America.
Because uptime is not something you hope for. It’s something you build.